From there, you validate the choice with Monte Carlo simulation and walk-forward testing before you trust it with real capital. Every sizing decision needs realistic cost modeling baked in. A backtesting environment and testing notes both build around this exact sequence.
TL;DR:
- Risk modeling must include realistic costs like slippage, commissions, and lot sizes to ensure backtest results reflect real trading conditions.
- Fixed-percentage and ATR-scaled sizing are generally more reliable for long-term growth because they adjust to account and volatility changes.
- Backtests should incorporate equity caps, timing of updates, and handling of same-day re-entries to avoid overestimating position sizes and accuracy.
- Monte Carlo simulations and walk-forward validation with out-of-sample data are essential to assess the robustness and tail risk of sizing strategies.
- A minimum of 30 to 100 trades is recommended for reliable backtesting, but larger samples provide better confidence in the results.
Table of Contents
- What Position Sizing Methods Should You Backtest First?
- How Do You Build Position Sizing Into a Backtest Engine?
- Which Metrics Actually Tell You a Sizing Model Is Better?
- Why Do You Need Monte Carlo and Walk-Forward Testing?
- What Pitfalls Distort Position Sizing Backtest Results?
- Romans' Perspective: Discipline Beats Peak Returns
- Run Your Own Position Sizing Backtest With Trade4
- Selected Sources and Further Reading
- FAQ
What Position Sizing Methods Should You Backtest First?
Position sizing only amplifies an edge that already exists. If your entry and exit rules produce negative expectancy, no sizing scheme fixes that; it just changes how fast you lose money. Once you've confirmed positive expectancy, the sizing method you choose determines whether your equity curve grows smoothly or whips around like a rollercoaster.
Here's how the main approaches stack up in a backtest matrix:
- Fixed-dollar sizing. You risk a flat dollar amount per trade regardless of account size or volatility. Simple to code, but it ignores account growth and instrument volatility, so it's rarely the right long-term choice for a serious backtest.
- Fixed-percentage sizing. Position size = (Account × risk %) ÷ (stop distance per unit). Risking 1% to 2% of equity per trade is the baseline most professionals default to, because it scales with your account and forces discipline on losing streaks.
- ATR or volatility-scaled sizing. This refines fixed-percentage sizing by letting Average True Range set the stop distance, which keeps dollar risk consistent whether you're trading a quiet large-cap or a small-cap that moves 8% intraday. Treat ATR as a complement to the fixed-percentage formula, not a replacement for it: ATR sets the stop, the risk percentage sets the size.
- Kelly and fractional Kelly. The Kelly Criterion calculates the mathematically optimal fraction of capital to risk based on win rate and payoff ratio. Full Kelly is aggressive enough to produce brutal drawdowns even with a genuine edge, so most practitioners test at 0.25× to 0.5× Kelly instead. If you trade volatile instruments like crypto, the math behind fractional Kelly sizing is worth studying closely before you code it into a backtest.
- Pyramiding and scale-in sizing. Adding to a winning position as it moves in your favor, or sizing contracts and lots for futures and options separately from equity-based percentage risk.
For a strategy with wide swings in win rate or payoff, fractional Kelly deserves a dedicated backtest run before you commit to it.
How Do You Build Position Sizing Into a Backtest Engine?
Getting the formula right is only the first step. The engineering details around it determine whether your backtest results mean anything.
The core calculation is simple: Position size = (Account × risk %) ÷ (stop distance per unit). The complexity lives in how you measure that stop distance and how you handle everything happening around it.
- Define your stop distance method. ATR-based stops (commonly 1.5 to 3 times the 14-period ATR) adapt to current volatility. Fixed-point stops and structure-based stops (below a swing low, for example) are alternatives, but each changes your position size differently for the same account risk.
- Set portfolio-level exposure caps. If you're running five setups simultaneously, cap aggregate risk (say, 6% of equity across all open positions) so a correlated move doesn't compound losses across unrelated trades.
- Decide when equity updates. Intraday systems that recalculate account equity mid-session will size differently than end-of-day systems. This timing choice materially changes available position sizes, and it's one of the most overlooked variables in backtest accuracy.
- Handle same-day re-entries explicitly. If a position opens, closes, and reopens within the same session, your backtest needs logic that prevents double-counting risk against the same capital. This is where a lot of homegrown backtests quietly break.
- Model execution realistically. Build in a slippage model, commission per trade, rounding to tradable lot sizes, and margin or notional behavior for leveraged instruments.
Small-cap and low-liquidity strategies need extra care here: minimum lot sizes and average daily volume create a real lower bound on position sizes, and backtests that ignore market impact on larger volume percentages will overstate returns. Trade4's approach to backtesting gap short strategies on small caps walks through exactly how liquidity constraints distort naive sizing assumptions.
Pro Tip: Log your position size calculation alongside every simulated trade, not just the trade outcome. When a backtest run looks off, the sizing math is usually where the bug is hiding, not the entry logic.
Which Metrics Actually Tell You a Sizing Model Is Better?
A sizing rule that boosts your CAGR but doubles your max drawdown isn't an improvement. It's a bet you haven't priced correctly yet.
Return-focused metrics come first, but they're incomplete on their own:
- CAGR (compound annual growth rate) shows the growth rate your sizing produced, but tells you nothing about the path taken to get there.
- Annualized volatility measures how bumpy that path was.
- Sharpe and Sortino ratios normalize return against volatility (Sortino only penalizes downside moves), letting you compare sizing schemes on a risk-adjusted basis.
Risk-focused metrics matter just as much, arguably more, because they tell you whether you'd have survived the ride:
- Maximum drawdown is the largest peak-to-trough decline your equity curve experienced under a given sizing rule.
- Time-to-recover measures how many trades or days it took to climb back to a prior equity high after that drawdown.
- MAR ratio (CAGR divided by max drawdown) is a fast way to compare sizing schemes on return per unit of pain.
R-multiples deserve their own attention. Van Tharp's R-multiple framework standardizes every trade result as a multiple of the initial risk taken (a trade that made twice what you risked is a "2R" win), which lets you compare sizing models independently of the underlying asset's price or unit size.
Statistic to watch: Van Tharp's research suggests 30 to 100 trades as a minimum baseline for a trustworthy R-multiple distribution, with larger samples in the hundreds materially improving confidence in what that distribution is telling you.
Visually, watch three things on your equity curve: whether it climbs in a reasonably straight line without violent kinks, how deep and how frequent your drawdown ladders are, and how tight the percentile bands from your Monte Carlo runs cluster around the median outcome.
Why Do You Need Monte Carlo and Walk-Forward Testing?
A backtest that only runs once on one historical sequence tells you how that sequence played out, not how your sizing rule behaves in general. Two techniques close that gap.
- Monte Carlo simulation. Reshuffle your trade sequence thousands of times, or bootstrap resampled trade sets, to build a distribution of possible equity curves rather than a single line. Look specifically at the 5th and 95th percentile outcomes: percentile bands expose the tail risk that a single average-case backtest hides completely, especially with more aggressive sizing like higher fractional Kelly multiples.
- Walk-forward validation. Split your historical data into rolling in-sample and out-of-sample windows. Tune your sizing parameters on the in-sample window, then test them unchanged on the out-of-sample window, and roll forward. A sizing rule that only works in-sample and falls apart out-of-sample is overfit, full stop.
- Parameter sensitivity sweeps. Run your backtest across a grid of risk percentages, stop multipliers, and Kelly fractions. If small changes to any one parameter produce wildly different results, your sizing rule is fragile, not robust, even if one specific combination looked great.
Sample size matters throughout. A modest minimum number of trades is generally recommended for reading an R-multiple distribution, but larger samples provide more confidence for Monte Carlo and walk-forward results. Trade4's guide to walk-forward validation and its piece on parameter sensitivity backtesting both walk through how to structure these sweeps without needing a custom database setup.
Pro Tip: If your walk-forward results degrade sharply the moment you move out-of-sample, don't just widen your parameter grid and try again. Go back and ask whether your in-sample window is even representative of the market regime you're testing against.
What Pitfalls Distort Position Sizing Backtest Results?
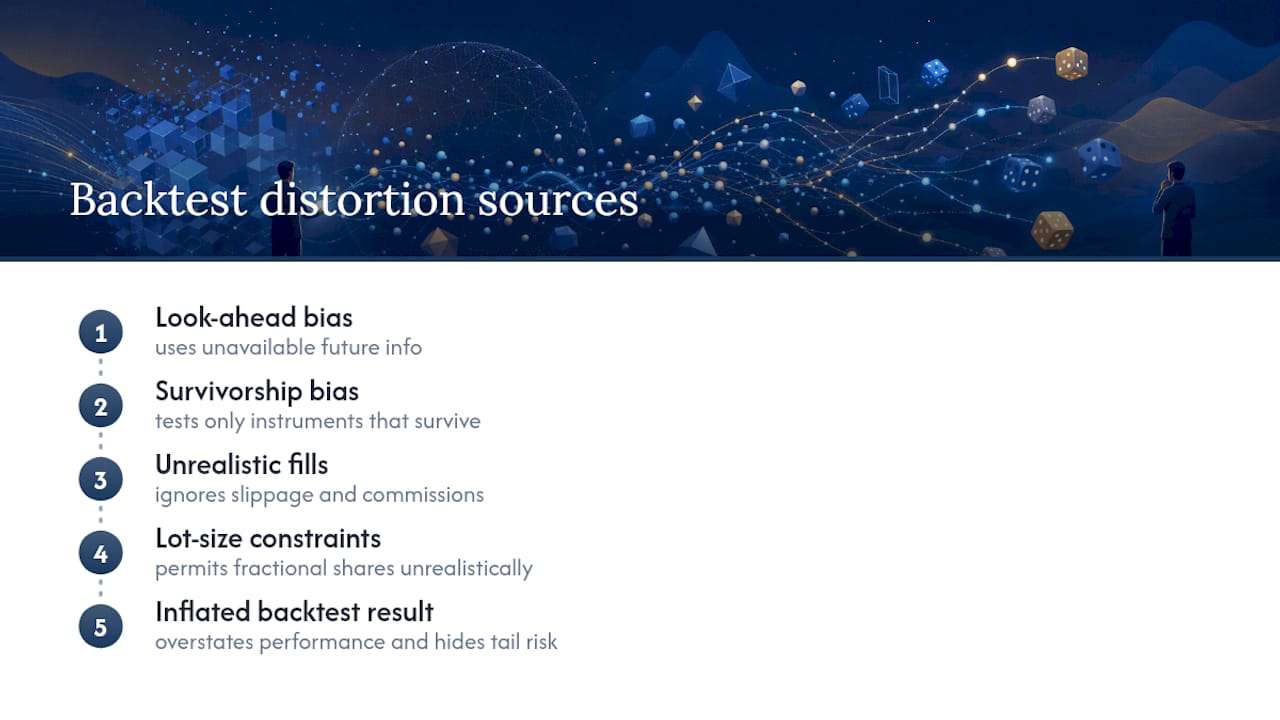
Several biases quietly inflate sizing performance in backtests: look-ahead bias (using information that wouldn't have been available at the time), survivorship bias (testing only on instruments that still exist today), unrealistic fills that ignore slippage, and lot-size constraints that let your backtest trade fractional shares no real broker would fill.
The subtler trap is over-optimizing your sizing parameters to a historical winning streak. A risk percentage or Kelly multiplier that looks perfect over one bull run often ignores the kind of gap-down or liquidity crunch that hasn't shown up yet in your sample.
Before any sizing rule goes live, run it through one checklist: confirm realistic costs (slippage, commissions, lot rounding) are modeled, confirm it passed walk-forward validation on genuinely out-of-sample data, check the Monte Carlo tail-risk percentiles rather than just the median outcome, verify your trade sample meets the minimum size guidance, and stress-test against at least one historical worst-case scenario, not just the average path.
Romans' Perspective: Discipline Beats Peak Returns
The traders who keep compounding are the ones who log every sizing decision and outcome, enforce a daily loss limit, and scale risk down as drawdowns deepen rather than doubling down to chase it back. Chasing the highest backtested return usually means signing up for the sizing rule most likely to blow up your account in a regime you haven't tested yet. Survivability compounds. Peak returns don't, if you're not still trading to see them.
— Romans
Run Your Own Position Sizing Backtest With Trade4
Everything above works better with a platform that lets you test it without writing custom database code. A no-code backtester offers tick-accurate historical data down to one-second granularity, same-day re-entry analytics that catch the double-counting errors described earlier, and multi-strategy runs so you can compare fixed-percentage, ATR-scaled, and fractional Kelly sizing side by side on the same trade set.

Inspect the equity curve for smoothness, the drawdown ladder for depth and duration, and the Monte Carlo percentile bands for tail risk before you touch a parameter sweep. If you're setting this up for the first time, the getting-started guide walks through configuring your first sizing test, and the Trade4 Backtester itself is where you'll actually run it against your own strategy data.
Selected Sources and Further Reading
- How to backtest a trading strategy step by step — Trade4 Blog
- Walk-forward validation practitioner's guide — Trade4 Blog
- Parameter sensitivity backtesting for fragile strategies — Trade4 Blog
- Kelly Criterion sizing for volatile assets
This article is general information, not a substitute for advice from a qualified financial advisor. Consult a qualified financial professional about your own circumstances before acting on anything here.
FAQ
What Is the Best Starting Point for a Position Sizing Backtest?
Validate it afterward with Monte Carlo simulation and walk-forward testing before adjusting further.
How Many Trades Do You Need for a Reliable Sizing Backtest?
Van Tharp's guidance suggests 30 to 100 trades as a minimum for a meaningful R-multiple distribution, though several hundred trades give you far more confidence in Monte Carlo and walk-forward results.
Can Position Sizing Fix a Losing Strategy?
No. Position sizing amplifies whatever expectancy your entry and exit rules already produce; it cannot turn a negative-expectancy strategy into a profitable one.
Is Full Kelly Sizing Safe to Backtest for Live Trading?
Full Kelly sizing tends to produce drawdowns too severe for most traders to tolerate psychologically or financially. Fractional Kelly, commonly 0.25× to 0.5× of the full calculation, is the more practical version to test and deploy.
What's the Difference Between Fixed-Dollar and Fixed-Percentage Sizing?
Fixed-dollar sizing risks the same dollar amount every trade regardless of account changes, while fixed-percentage sizing risks a consistent percentage of current equity, scaling automatically as the account grows or shrinks.